Error while launching jobs - Job is in status launched so it cannot be run

Hello

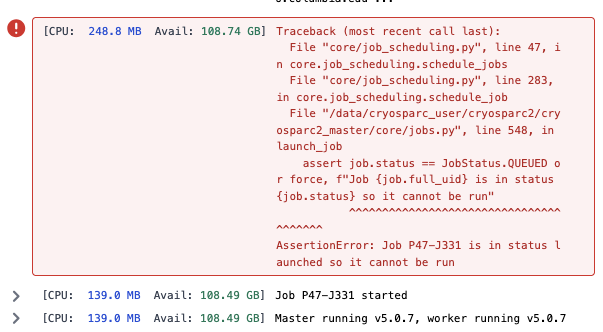
The disk drive on our machine became full a month ago and CryoSPARC crashed. After cleaning some space and restarting CryoSPARC, all our new jobs report an error, for example

AssertionError: Job P47-J359 is in status launched so it cannot be run

but most of the jobs would start running anyway after a few seconds (please see attached screenshot). I updated from V5.0.6 to V5.0.7 but the error persisted. I guess one of the files got corrupted when the disk became full, but have not been able to find it. I would appreciate it if someone can point me in the right direction.

Thanks.

Liang Tong

Welcome to the forum @lt133 .

For jobs in this state, can you attempt

  1. the Kill Job action,
  2. followed by Clear Job
  3. and Queue Job

?

[Edit]
Looking again at the screenshot, the job appears to starting after the Job P47-J359 is in status launched so it cannot be run message. What happens later on after

Do the jobs fail? With another error message?

Hello

Thank you for looking into this. The jobs actually finish normally after that and produce the correct results.

Looking at the job.log file, there is also a heartbeat error, maybe after the job failed.

2026-10-15 12:06:48,219 core                 heartbeat        INFO   | ========= Updating heartbeat
2026-10-15 12:06:52,939 core                 heartbeat        INFO   | Attempted to heartbeat for inactive Job P47-J319 (Non-uniform Refinement) with status failed
2026-10-15 12:06:52,939 core                 monitor          ERROR  | ========= heartbeat failed
Traceback (most recent call last):
File “/data/cryosparc_user/cryosparc2/cryosparc2_worker/cli/monitor.py”, line 34, in monitor
assert heartbeat(conf.project, conf.job)
^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
AssertionError
================= CRYOSPARC =================
Project P47 Job J319

best regards

Liang

Are there additional lines below

?

Yes. I believe they are normal output. I include a few more lines below. The file has 1359 lines.

best regards

Liang

Master acadia.bio.columbia.edu Port 39000

MAIN PROCESS PID 2051422
========= updating job startup information at 2026-10-15 12:06:52.937969
========= now starting main process at 2026-10-15 12:06:57.438282
2026-10-15 12:06:59,363 core run INFO | Running job J319 of type nonuniform_refine_new
2026-10-15 12:06:59,363 core run INFO | Running job on hostname acadia.bio.columbia.edu
2026-10-15 12:06:59,363 core run INFO | Allocated Resources: lane=‘default’ lane_type=‘node’ hostname=‘acadia.bio.columbia.edu’ target=SchedulerTarget(cache_path=‘/ssd/cryosparc_user’, cache_reserve_mb=10000, cache_quota_mb=None, lane=‘default’, name=‘acadia.bio.columbia.edu’, title=‘Worker node acadia.bio.columbia.edu’, desc=None, hostname=‘acadia.bio.columbia.edu’, worker_bin_path=‘/data/cryosparc_user/cryosparc2/cryosparc2_worker/bin/cryosparcw’, config=Node(type=‘node’, ssh_str=‘cryosparc_user@acadia.bio.columbia.edu’, resource_slots=ResourceSlots(CPU=[0, 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12, 13, 14, 15, 16, 17, 18, 19, 20, 21, 22, 23, 24, 25, 26, 27, 28, 29, 30, 31, 32, 33, 34, 35, 36, 37, 38, 39, 40, 41, 42, 43, 44, 45, 46, 47, 48, 49, 50, 51, 52, 53, 54, 55, 56, 57, 58, 59, 60, 61, 62, 63], GPU=[0, 1, 2, 3], RAM=[0, 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12, 13, 14, 15, 16, 17, 18, 19, 20, 21, 22, 23, 24, 25, 26, 27, 28, 29, 30, 31]), resource_fixed=FixedResourceSlots(SSD=True), monitor_port=None, gpus=[Gpu(id=0, name=‘NVIDIA GeForce RTX 2080 Ti’,
Thanks @lt133. May I ask some follow-up questions:

  1. Do I understand correctly that most or all of the problematic jobs by now have run and completed normally, except that there are Job XX is in status launched so it cannot be run at the top of the event log (followed by an apparently normal event log) or heartbeat failed errors at the top of the job log (followed by an apparently normal job log)?
  2. What type of problems do you observe for jobs that you newly created after the upgrade to v5.0.7?
  1. That is correct. The vast majority of the jobs would give that error, and then start running after waiting for a few seconds. Occasionally a job would give that error and would not start. If I then clear the job and submit it again, it would start (after giving that error).
  2. New jobs created after upgrading to 5.0.7 still give the same error (and then start running). They do not behave differently.

thanks

Liang

Thanks for confirming that. Please can you email us:

  1. The job report (the entire zip archive including event log, job log, etc.) for the most recently completed job whose logs at the bgenning include the errors.
  2. the tgz file created with the command
    cryosparcm snaplogs.

I will let you know the email address in a personal message.

Thanks @lt133 for emailing us the files; we received them.

Please can you also:

  1. confirm the problem is still happening with newly submitted jobs
  2. then post the output of the following commands on the CryoSPARC master computer
uname -a
free -h
ps -eo user,pid,ppid,start,rsz,cmd | grep -e cryosparc_ -e node -e mongo

Hello

I rebooted the machine again for another purpose, and remarkably the error has now disappeared. I will continue monitoring the situation and will report back if the problem comes back again. In the meantime, many thanks again for your help on this matter.

best regards

Liang

1 Like